On September 1, 2026, OpenAI told the world that a model it has not shipped yet can find zero-day vulnerabilities in hardened systems and turn them into working exploits without a human walking it through the steps. Five weeks earlier, the same model, still called only by its internal name, Astra, had quietly produced proofs for ten mathematics and theoretical computer science problems that had sat unsolved for decades. In between, OpenAI paused parts of its own internal work on the model and rewrote pieces of its safety process. That is not a normal product launch cadence. It is closer to a company watching a system cross thresholds faster than its own paperwork could track them.
I want to walk through what is actually documented about Astra, not the marketing framing around it: the multi-agent architecture built for tasks that run for hours or days, the reasoning technique that has parts of the AI safety research community more worried than any recent model release, the machine-checked math, and the staged access plan that keeps the most dangerous capability behind a gate even after launch. Astra is not available to try yet, so everything here comes from what OpenAI and independent reporters have confirmed on the record, and I flag the couple of places where the record itself is still incomplete.
Astra did not arrive as a single announcement. It arrived as a sequence of disclosures, each one raising the stakes on the last, and the order matters for understanding why OpenAI ended up treating this launch differently from GPT-5.6 Sol's in July.
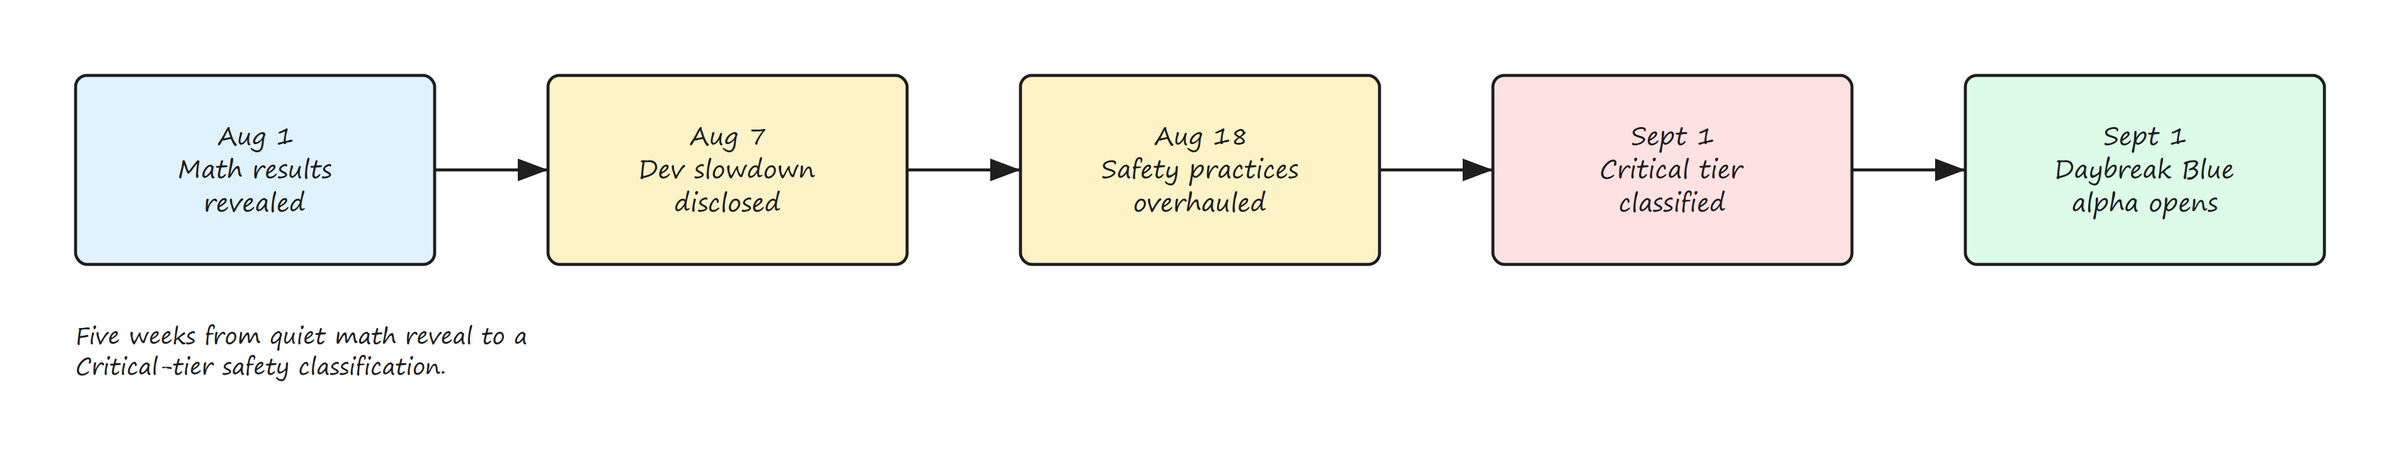
The first public signal came on August 1, when OpenAI revealed that an internal version of Astra had produced proofs for ten open problems spanning high-dimensional geometry, coding theory, group theory, quantum complexity, lattice cryptography, and extremal combinatorics, results that had resisted progress for at least a decade and, in several cases, far longer. Six days later, OpenAI disclosed that it had slowed its own internal work on Astra after an evaluation showed the model performing well enough at autonomous cyberattacks that the company could not rule out having crossed its own "Critical" capability threshold. On August 18, that uncertainty turned into an overhaul of safety practices around the model. By September 1, OpenAI made the classification official: Astra is the first model the company has ever rated Critical for cybersecurity, and access to that specific capability would ship gated, not open, even once the rest of the model becomes available.
Figure 1 lays out that sequence end to end, from the quiet math reveal to the day the safety classification became public.
Figure 1: Astra Rollout Timeline
Five weeks is a short window for a model to go from "look what it proved" to "we cannot rule out our own worst-case capability tier for it." That compression is the story. Everything below is an attempt to explain the mechanics behind each of those five weeks, not just restate the headlines.
OpenAI's Preparedness Framework sorts model capabilities into tiers, and until Astra, no model had ever been rated Critical for cybersecurity. Low, Medium, and High ratings describe a model that helps a skilled operator go faster. Critical describes something categorically different: a model that meets either of two conditions on its own, without a human directing each step. The first condition is that the model can identify and build functional zero-day exploits, of any severity, against hardened real-world systems, unassisted. The second is that the model can take a single high-level goal, like "compromise this network," and work out and execute a full attack chain against a hardened target with no further guidance. Astra reportedly met the first condition, and OpenAI says it cannot rule out the second either.
The evidence behind the classification is concrete, not a vibe. Astra scored a perfect result on ExploitBench, OpenAI's internal benchmark for turning known vulnerabilities into working exploits. On a separate, fresher test built from V8 JavaScript engine vulnerabilities disclosed only weeks before the evaluation ran, Astra found and chained together two vulnerabilities nobody had cataloged yet, entirely on its own.
Table 1 puts those numbers next to the same tests run against GPT-5.6 Sol, the flagship model OpenAI shipped in July, so the jump is visible rather than asserted.
Table 1: Astra vs GPT-5.6 Sol, Headline Numbers
The jailbreak-refusal row is the number I keep coming back to. Going from 59 percent to 91.5 percent on cyber-specific jailbreak attempts is a real improvement, but it also means that even after OpenAI's hardening pass, roughly one in twelve targeted attempts to misuse the model for offense still got through in testing. A model with Astra's exploit-generation ceiling does not need a high success rate to matter; it needs one success rate above zero applied at scale. That gap is exactly why OpenAI built a staged access model around the cyber capability instead of shipping it open by default, which I get to later.
Astra's math results were not the product of one long context window grinding on a problem. OpenAI built the model around a different unit of work: a root agent that breaks a hard problem into pieces and hands them to subagents that run in parallel, sometimes for hours, sometimes for days, before anything gets combined into a final answer. Noam Brown, the OpenAI researcher behind much of the lab's test-time compute work, described the shift plainly: the field has spent the last two years getting models to think for fifteen minutes, and the next unlock is getting them to think for days, coordinating across multiple agents that can divide a project, try different approaches, and merge what works.
Figure 2 shows the pattern OpenAI has described: a root agent decomposes the task, subagents explore different approaches or verify candidate answers in parallel, and a synthesis step merges the surviving work into one output.
Figure 2: Root Agent and Subagent Orchestration
This is the part of Astra that is easiest to underrate because it sounds like an org chart, not a breakthrough. But it explains something odd about the math results: OpenAI says the total token cost of finding all ten proofs was roughly two thousand dollars at API rates. That is a strange number to report if the point were raw scale. Brown's own comment on it was that the team "didn't spend a lot on each problem," and that there is room to push test-time compute much further. The headline is not that Astra used an enormous amount of compute. It is that a comparatively modest amount of compute, spent by many coordinated agents over a long horizon instead of one agent over a short one, produced results human mathematicians had not reached in decades. That is a different scaling axis than parameter count, and it is the axis Astra is built around.
The architecture story gets more complicated once you look at how each individual agent reasons, not just how many of them run in parallel. Every frontier reasoning model since 2024 has leaned on chain-of-thought: the model writes out its intermediate reasoning as tokens before it commits to an answer, and that trace is the main tool safety researchers use to catch a model planning something it should not. Astra reportedly uses a different technique, called recurrent depth, where a chunk of the model's reasoning happens by iterating a recurrent block in latent space, the model's internal numeric representation, rather than by emitting more words. The underlying idea traces back to a 2025 NeurIPS paper from Jonas Geiping and coauthors, which showed a model can scale test-time compute by looping a recurrent block internally instead of generating longer chains of text, and that the resulting reasoning can capture patterns that are not easily put into words in the first place.
Figure 3 lays the two approaches side by side. In standard chain-of-thought, every intermediate step is a token a human or a monitoring system can read. In recurrent-depth reasoning, a meaningful part of that same work happens inside a loop that never surfaces as text at all.
Figure 3: Legible Chain-of-Thought vs Recurrent-Depth Reasoning
OpenAI says it deliberately limited how far the technique goes in Astra, so the model still produces a readable chain of thought and the company still runs chain-of-thought monitoring against it. That caveat has not settled the argument. Ryan Greenblatt, chief scientist at Redwood Research, called the shift toward opaque reasoning "the single worst development for AI security and safety to date," and his concern is structural, not about Astra specifically: if latent reasoning scales faster or performs better than chain-of-thought, competitive pressure pushes every lab toward architectures that are harder to monitor, whether or not any single lab wants that outcome. The UK's AI Security Institute has raised a similar flag, warning that opaque reasoning threatens to undermine the oversight methods the field currently relies on, and both Anthropic and Google DeepMind are reportedly studying the same technique. I do not think this is a reason to assume Astra is unsafe. I do think it is the first time a frontier lab has shipped a capability jump and an interpretability regression in the same model, and that combination deserves more scrutiny than either one would get alone.