Arithmetic Intensity, Hardware Ceilings, Iteration-Level Continuous Batching, and the 2026 Production Serving Blueprint
*Technical Analysis & Systems Synthesis by *DistributedApps.ai | Synthesizing frontier research from DeepSeek, Moonshot AI, Zhipu AI, Alibaba, NVIDIA, and Google DeepMind into production engineering blueprints.
Free Edition: Comprehensive Chapter Roadmap
Below is the complete architectural roadmap covered in this chapter:
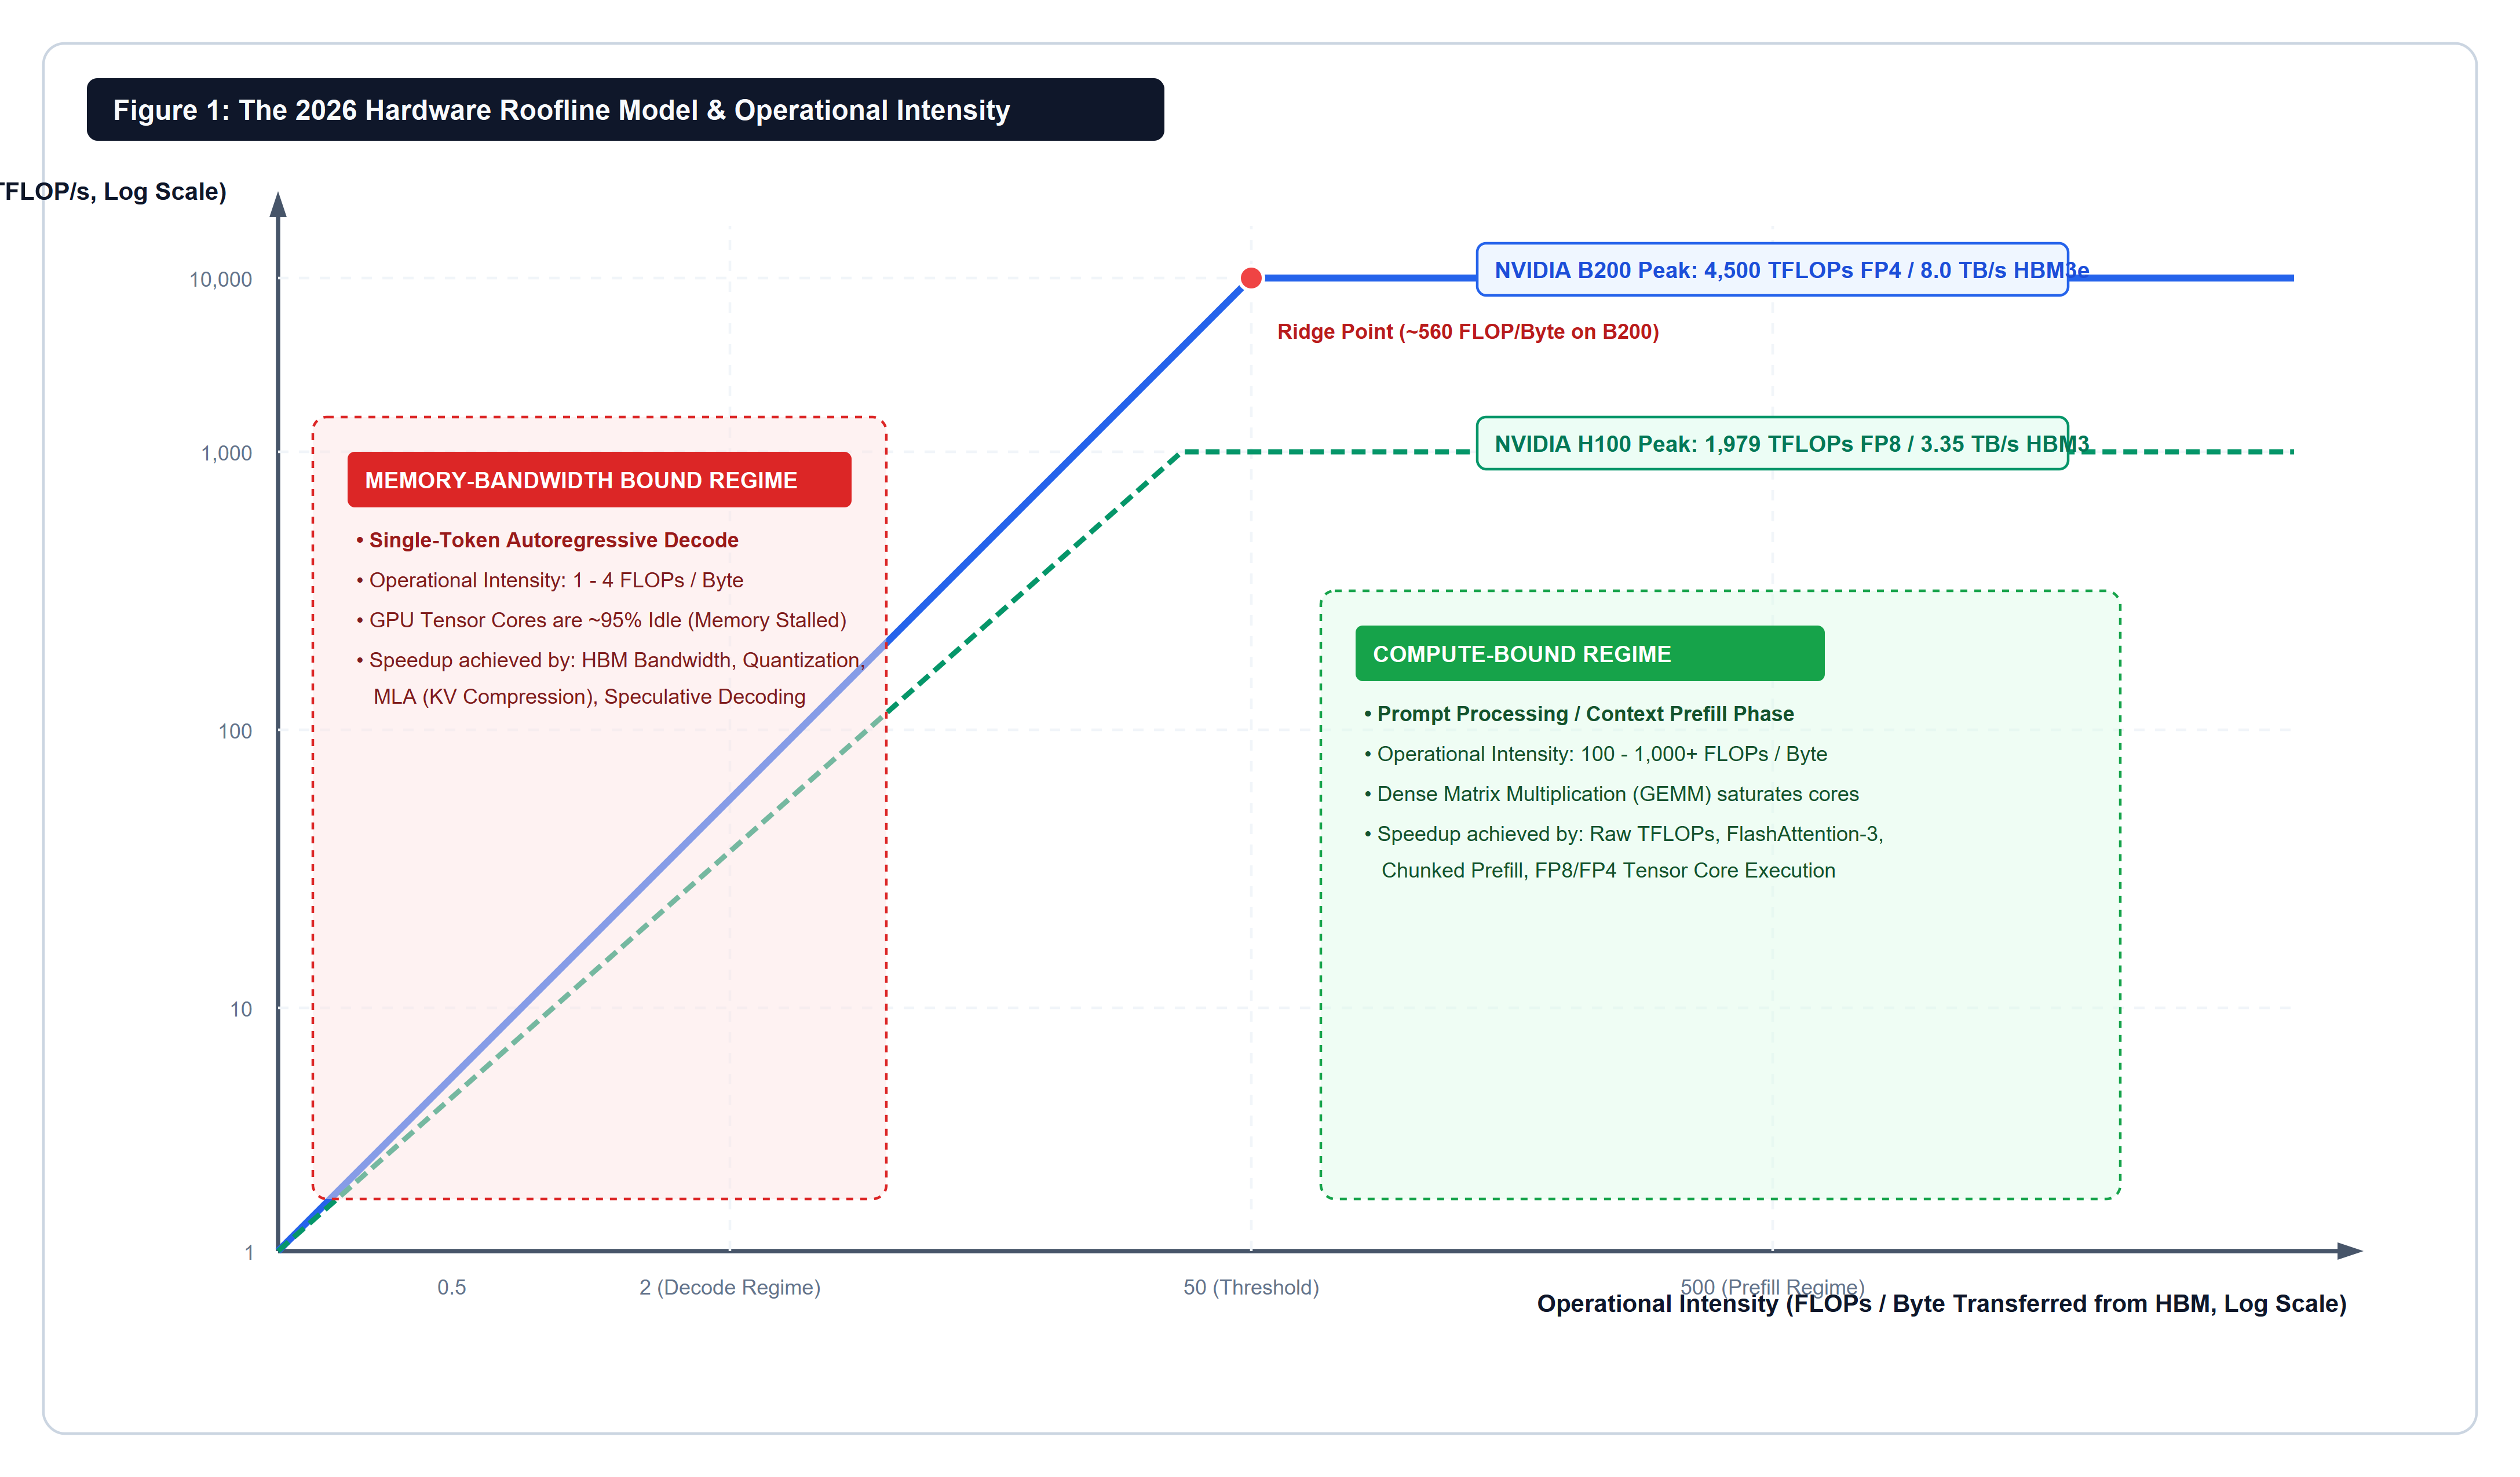
Foundational Physics: Breaking the Memory Wall & Arithmetic Intensity: Microarchitectural roofline modeling across NVIDIA Hopper H100 and Blackwell B200 accelerators.
The Memory Allocation Hierarchy & VRAM Capacity Bottleneck: Exact memory accounting for model weights, dynamic KV activations, and CUDA workspaces.
The Prefill-Decode Dichotomy & Streaming Multiprocessor Contention: Why high-arithmetic-intensity prompt prefill and memory-bound autoregressive decoding create execution bubbles when co-located.
Evolution of Batching Systems: Static, Continuous & PagedAttention: From early static batching waste to Orca iteration-level continuous scheduling and vLLM virtual memory paging.
Production SRE & Cluster Telemetry: Measuring TTFT, Inter-Token Latency (ITL) P99 SLOs, and memory fragmentation in mission-critical deployments.
Discrete-Event Simulation & Capacity Planning: Python simulator modeling queue delays, scheduling policies, and multi-tenant goodput.
⚡ Subscriber-Only Deep Dive Beyond This Point
To access the complete technical treatise, production code repositories, Triton/CUDA kernels, and infrastructure sizing templates for this chapter, upgrade to a paid subscription today.
Special Offer: Get 50% OFF the annual subscription to the 2026 Foundation Model Inference Series using the link below:
👉 Unlock Full Access with 50% Off Annual Pass 👈
Read more