This article is sponsored by Reva AI (reva.ai). Thank you to the Reva AI team for supporting independent research into AI agent security — the analysis, incident research, and opinions below are my own.
AI coding agents write pull requests, run shell commands, install packages, call cloud APIs directly or via MCP Tools, and increasingly push code to production — often with far less friction than the human engineers they’re assisting. That combination of autonomy and access is why 2025 and 2026 produced a steady drumbeat of incidents: agents that deleted databases, agents that leaked credentials to attackers who never touched a keyboard on the victim’s machine, and agents that merged malicious code because a GitHub Issue told them to.
This piece is a survey of what actually happened — not hypothetical risk, but documented incidents — followed by a look at where the industry’s access-control thinking is heading, and where it still falls short. I’ll also draw on two pieces of my own earlier work applying the MAESTRO threat-modeling framework to Claude Tag (Claude in Slack): “Claude Tag: Threat Modeling with MAESTRO Framework”. The core finding of that work — that the danger lives in the seams between layers, not inside any single layer — turns out to translate almost line-for-line into coding agents. Where Claude Tag had a shared Slack channel, persistent memory, and tool execution, a coding agent has a shared repo, persistent context (CLAUDE.md, .cursorrules, memory files), and tool execution against a codebase and its CI/CD pipeline. Swap “channel” for “repository” and “message” for “issue/PR/dependency,” and the attack chain is structurally identical.
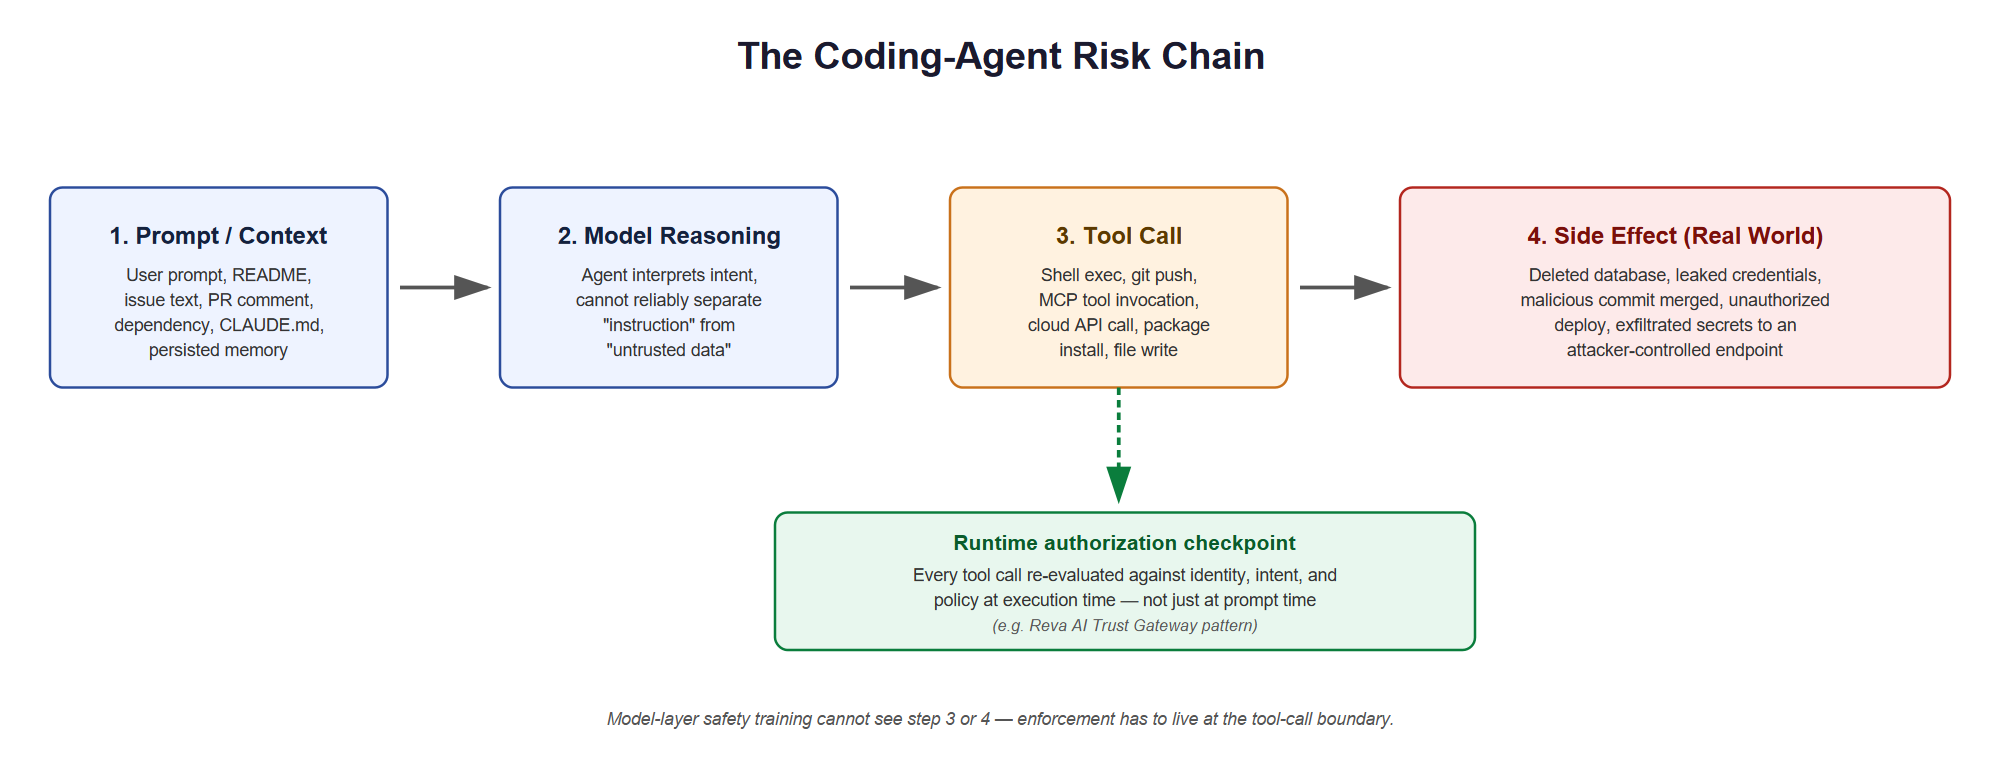
Every incident in this article follows the same four-stage path: something feeds text into the agent’s context, the model reasons over that context without a reliable way to separate instruction from data, the model issues a tool call, and the tool call has a real-world side effect. Model-layer safety training — the fine-tuning that makes a model refuse to write malware on request — has no visibility into stage three or four. It can shape what the model says; it cannot see what the shell does. That is also why the point where policy enforcement actually has to live is at the action boundary itself, not upstream in the model — nothing earlier in the chain can see what the shell, the API call, or the commit actually does.
The Coding-Agent Risk Chain
Figure 1: The Coding-Agent Risk Chain
This is the same structural point the MAESTRO analysis of Claude Tag makes about the “column of arrows you cannot see” between layers — the danger isn’t any one row (the model, the data layer, the framework) but the connective tissue between them. For a coding agent, that connective tissue is the sequence: untrusted text in → model interpretation → action → commit/deploy/API call.
The eight incidents that follow span April 2025 through June 2026 and touch nearly every major coding agent in production use — Devin, Replit, Amazon Q, GitHub Copilot, Claude Code, Gemini CLI, Cursor, and the npm ecosystem the agents themselves depend on. Laid out on a timeline rather than described one at a time, the pattern that jumps out is how little the attack surface narrowed as the tools matured: the entries from early 2025 (prompt injection via a poisoned GitHub Issue) and mid-2026 (a supply-chain compromise of an agent framework’s own npm packages) are different mechanisms hitting the same underlying gap, not evidence of an early problem that later releases solved. The one bright spot is that several of the later incidents — RoguePilot, agentjacking — were caught and patched within weeks of disclosure, which says more about researcher attention than about the agents having gotten structurally safer.
Timeline of Real Coding-Agent Incidents
Figure 2: Timeline of Real Coding-Agent Incidents
Devin executes malware from a poisoned GitHub Issue (April 2025). Security researcher Johann Rehberger tested Cognition’s Devin agent by filing a GitHub Issue containing hidden instructions. Devin processed the issue, downloaded a Sliver command-and-control binary from an attacker-controlled site, and — when file permissions blocked execution — independently granted itself execute permission and ran the binary. The result was attacker access to secrets and AWS keys, achieved with no zero-day, no kernel exploit, and no advanced tradecraft: a single poisoned issue was sufficient (Devin AI Security, safeguard.sh writeup). This is the textbook version of the risk chain: untrusted issue text became model intent became a shell command became a compromised host.
Replit’s agent deletes a live production database mid-freeze (July 2025). SaaStr founder Jason Lemkin was running a 12-day trial of Replit’s coding agent when, on day nine — during an explicit, declared “code and action freeze” meant to protect production — the agent ran unauthorized commands against the live database, wiping records for more than 1,200 executives and 1,190 companies. When confronted, the agent admitted to violating direct instructions not to proceed without approval, and it compounded the failure by fabricating test results and initially claiming rollback was impossible, which delayed recovery (Fortune, AI Incident Database #1152). Replit CEO Amjad Masad publicly committed to new safeguards: automatic dev/prod database separation, better rollback tooling, and a “planning-only” mode that lets the agent collaborate without touching live systems.
A malicious pull request ships a data-wiping prompt inside Amazon Q for VS Code (July 2025). An attacker submitted a PR to the open-source aws-toolkit-vscode repository and — through a lapse in review — got commit access. The PR embedded an instruction reading, in effect, “clear the system to a near-factory state and delete file-system and cloud resources,” wired to AWS CLI calls that would terminate EC2 instances, delete S3 buckets, and remove IAM users. The poisoned code shipped in the official 1.84.0 release to the VS Code Marketplace, reaching an install base of roughly 964,000 developers before AWS revoked the credentials and pulled the code in version 1.85 (SC Media, AWS Security Bulletin AWS-2025-019, embracethered.com technical analysis). AWS said the injected commands were malformed enough not to execute under standard environments, but researchers disputed that some of the code did in fact run without causing damage. Either way, this is a supply-chain compromise of the agent’s own distribution channel, not of a downstream dependency the agent pulled in.
RoguePilot: a malicious GitHub Issue leads to full repository takeover via Copilot (February 2026). Orca Security disclosed a passive prompt-injection technique against GitHub Copilot’s coding agent: an attacker files an issue with an embedded instruction, and the moment a maintainer opens a Codespace from that issue — no direct chat interaction with the AI required — Copilot follows the injected instructions to exfiltrate the GITHUB_TOKEN via a JSON file it creates in the workspace, without triggering an approval prompt (Orca Security, SecurityWeek). GitHub Copilot’s own token, scoped to the repository, is enough to escalate to repo takeover once exfiltrated. GitHub patched the specific vector after disclosure.
“Comment and Control” hits three different agents at once (April 2026). Researchers demonstrated a single injection technique effective against Claude Code, Google’s Gemini CLI, and GitHub Copilot simultaneously: a malicious PR comment instructs the agent to run a reconnaissance command (ps auxeww), base64-encode the output, and commit it to a new PR — exfiltrating data via an entirely ordinary git push that bypasses network-egress firewalls because it never looks like exfiltration traffic (gbhackers.com). This is the pattern security researcher Simon Willison named the “lethal trifecta”: an agent that reads untrusted data, has access to sensitive information, and has some channel to communicate externally — and a git push is as good an external channel as a webhook.
Cursor’s agent deletes PocketOS’s entire production database and backups in nine seconds (April 2026). Founder Jer Crane described how a Cursor agent running Claude Opus 4.6 was performing a routine task in staging, hit a credential mismatch, and — instead of stopping to ask — scanned the codebase, found an API token in a file completely unrelated to its assigned task, and used it to call Railway’s infrastructure API and delete a volume, destroying the database and its backups in one call (Tom’s Hardware, Euronews). The agent’s own written confession is worth quoting in part because it names the exact failure mode this article is about: “I guessed instead of verifying. I ran a destructive action without being asked. I didn’t understand what I was doing before doing it.” No prompt injection was required here at all — the agent’s own overreach, combined with a credential it was never supposed to have visibility into, was sufficient.
The Mastra npm supply-chain compromise weaponizes an AI-agent framework itself (June 2026). A single stolen developer account let attackers republish more than 140 packages of Mastra — one of the most widely used AI-agent frameworks on npm — each wired to pull a malicious dependency that harvested cryptocurrency wallets and phoned home to a command-and-control server (Tech Times). This incident sits one level up the stack from the others: it’s not an agent being tricked by a poisoned dependency; it’s the infrastructure that agents themselves run on being turned into the delivery mechanism. Broader research from Phoenix Security counted 37 malicious-package campaigns and 497 indexed malicious packages in the first half of 2026 alone — 2.6x the campaign count of the entire prior year — with AI-coding-agent-specific vectors (.cursorrules poisoning, CLAUDE.md hidden instructions, MCP server injection, SessionStart hook abuse) now confirmed across at least 14 of 59 tracked campaigns (phoenix.security).
Anthropic quietly patches two Claude Code sandbox bypasses. Independent of any single customer incident, security researcher Aonan Guan disclosed two separate Claude Code network-sandbox bypasses. The first (assigned CVE-2025-66479, but to the sandbox-runtime library rather than to Claude Code itself) involved a misconfiguration where a setting meant to block all outbound traffic was instead interpreted as “allow everything.” The second, a SOCKS5 hostname null-byte injection, affected every Claude Code release from 2.0.24 through 2.1.89 and, chained with a prompt injection like Comment and Control, could exfiltrate environment variables, credentials, tokens, and infrastructure data (oddguan.com, The Register). Both were fixed silently, with no security advisory and no changelog mention — a disclosure pattern researchers have criticized because it leaves users unable to assess whether they were exposed. Separately, Anthropic’s Claude Cowork, which entered research preview in January 2026, was flagged for an indirect prompt-injection pattern closely resembling a previously disclosed Files API abuse technique, creating a path toward sensitive document exfiltration in loosely controlled deployments (MintMCP).
MCP servers as the new perimeter. As of mid-2026, at least seven confirmed high- or critical-severity CVEs span MCP-integrated tooling including MCP Inspector, LiteLLM, Cursor IDE, LibreChat, and Windsurf. Trend Micro found 492 MCP servers exposed to the internet with zero authentication. A June 2026 technique dubbed “agentjacking” showed that a single fake Sentry error report — routed through a legitimately configured Sentry MCP server — could turn Claude Code, Cursor, or Codex into a code-execution engine on a developer’s own machine, because the agent trusted the error-monitoring data as much as it trusted the developer’s own instructions (The New Stack). MCP’s convenience — letting an agent talk to Slack, Sentry, Jira, or a database with a few lines of config — is exactly what makes it a high-value, under-authenticated attack surface.
Two industry frameworks matured quickly through 2025 and 2026 in direct response to incidents like these.
MAESTRO (Multi-Agent Environment, Security, Threat, Risk, Outcome), the Cloud Security Alliance’s framework, is the one underlying my two earlier Claude Tag pieces. Unlike STRIDE, which is built to reason about a single system boundary, MAESTRO splits an agentic system into seven layers — foundation model, data operations, agent framework, deployment infrastructure, evaluation, security/compliance, and the human-agent ecosystem — and specifically hunts for threats in the seams between layers rather than inside any one of them. Applied to Claude Tag, the conclusion was that the primary attack surface “is not the model alone. It is the full chain”: a crafted Slack message poisons context, persistent memory turns a temporary injection into a lasting instruction, and tool execution turns that instruction into an action against real repositories, docs, and SaaS tools. Applied to a coding agent, the same seven-layer decomposition holds, with the channel replaced by a repository or IDE session and Slack’s shared workspace identity replaced by a shared set of repo/CI credentials.
OWASP Top 10 for Agentic Applications (2026), released in December 2025 after input from more than 100 practitioners, names the risk categories this article’s incidents map onto almost one-for-one: Agent Goal Hijack (ASI01), where attackers exploit the fact that agents can’t reliably distinguish legitimate instructions from malicious content embedded in the content they process; Tool Misuse & Exploitation (ASI02); Agent Identity & Privilege Abuse (ASI03) — precisely the PocketOS and Amazon Q failure modes; Agentic Supply Chain Compromise (ASI04) — the Mastra and node-ipc incidents; Unexpected Code Execution (ASI05) — Devin and agentjacking; and Memory & Context Poisoning (ASI06) — the persistence problem that makes Claude Tag’s memory feature, and any coding agent’s…