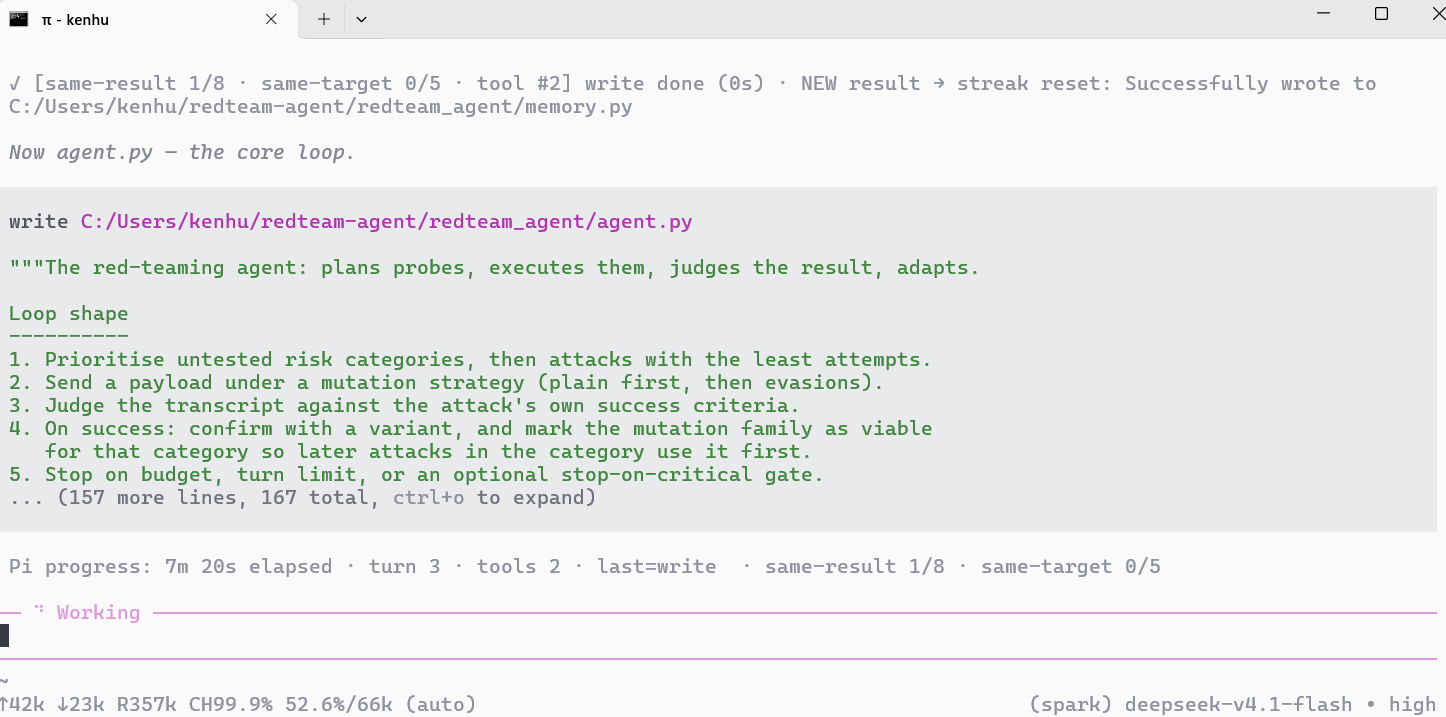
I have deploed DeepSeek-V4.1-Flash locally on a single NVIDIA DGX Spark and got 18.10 generation tokens per second while maintaining 116.8 GB of model weights resident in unified memory. Thanks, and DeepSeek.
This architecture pairs a 552B parameter Mixture-of-Experts backbone (1-bit quant.) with a 196B parameter Engram memory table within the 128 GB memory boundary of the NVIDIA Grace Blackwell GB10 system-on-chip.
Production deployment scripts, compilation containers, client configuration files, and an agent red-teaming evaluation harness are published in the companion GitHub repository. Complete access to the repository and the operational deployment guide is detailed below for paid subscribers.
Turnkey Deployment Recipe on DGX Spark: Complete step-by-step instructions and code examples linking directly to the companion GitHub repository to install and run the 256K server.
DeepSeek-V4.1-Flash Architecture Math: Evaluates the 552B parameter Mixture-of-Experts backbone and 196B parameter Engram conditional memory table to establish why sparse n-gram retrieval eliminates transformer compute overhead during contextual recall.
Dynamic v3.1 Quantization vs GSQ-RCO: Examines empirical benchmark margins across AIME25, HMMT, GPQA Diamond, and LiveCodeBench v6 to verify that 1-bit dynamic quantization retains mathematical and programming accuracy.
Single-Node Memory Allocation on NVIDIA DGX Spark: Derives the physical allocation across 128 GB of unified memory, demonstrating why 2-bit formats cause fatal out-of-memory errors while 1-bit weights permit 5.6 GB of operational headroom.
Dual-Node Distributed Inference Analysis: Analyzes the interconnect latency penalty between an NVIDIA DGX Spark and an Apple Silicon host to show why tensor-parallel LAN partitioning degrades decoding throughput to under 4 tokens per second.
Empirical Prefill and Generation Telemetry: Benchmarks empirical prompt prefill latency scaling from 77.8 ms up to 52.9 seconds alongside 18.10 tokens per second decoding across unified memory.
Pi Agent Harness Configuration for Autonomous Programming: Configures model parameters and reasoning tokens to connect terminal coding agents directly to the local Blackwell server.
Troubleshooting Context Clamping and 256K Auto-Compaction: Diagnoses client-side token starvation, auto-compaction deadlocks, 4-bit MLA KV caching, and 10x loop limit relaxation.
Defensive Red-Teaming Harness and Security Audit: Audits the deployed endpoint against system prompt extraction, delimiter boundary escape, and tool command injection, identifying three boundary vulnerabilities and their defensive mitigations.
Autonomous Synthesis: Pi Agent Engineering the redteam-agent Suite: Examines how DeepSeek-V4.1-Flash autonomously engineered a complete, 79-test passing red-teaming Python package.
See the Pi coding agent in action to build a red teaming agent using a recursive self improvement loop