The Story So Far
Mechanistic interpretability is the science of “reading an AI’s mind”.
Large language models are “grown, not built”. Researchers run training data through a neural network. Eventually this creates a working AI; nobody really knows how.
But a neural network is just a set of simulated neurons on a computer. The person with the computer can see the neurons, the connections between them, and which ones activate when the AI answers questions. So it seems like it should be possible to “reverse engineer” the AI. This would be scientifically useful: understand how AIs work, with possible relevance to human cognition. It could also be practically useful: find the circuits responsible for dishonesty, hallucination, bias, and other negative behaviors, then redesign those circuits.
Unfortunately this is very hard. A modern AI has millions of neurons and trillions of connections between them (aka “parameters”, “weights”). Their structure is apparently nonsensical: researchers started by seeking a 1:1 mapping between neurons and concepts, like a neuron that always fired when the AI was thinking about cats, but quickly learned that nothing like that existed.
Their first big breakthrough came in 2023. Rather than a 1-to-1 neuron-to-concept mapping, they discovered a many-to-many mapping. Neurons 1 and 2 firing together might mean cat; 1 and 3 firing together might mean chair; 2 and 3 firing together might mean bread. Such mappings let AIs with “only” tens of thousands of neurons represent millions of concepts. There were far too many of these combinations for humans to map, but researchers set other, smaller AIs to mapping them and met with some early success - like this functional combination of neurons (“feature”) representing “God” in an artificially-simple 512-neuron AI:
Spirits were high. Scale up the AI interpreter, and maybe we could do anything! Philosophers could discover the fundamentals of cognition. Doomers could solve alignment by tracing the circuits involved in moral reasoning. Tens of millions of dollars poured into the field. Superstar interpretability researcher Chris Olah got an audience with the Pope (okay, fine, this was mostly unrelated).
By 2024-2025, the clarity of many-to-many mapping had dissolved, and everyone was back to feeling confused and miserable. Strategies that had successfully analyzed artificially-simple research-subject AIs failed to work on real language models. Different teams making many-to-many maps of the same AI reported different results. And humans watching supposedly-mapped AIs more closely found that seemingly-crisp features were much vaguer and worse than previous analysis had led them to believe: a feature which they thought meant “God” might activate on any vaguely religious or awe-inspiring text, or even text with no logical connection whatsoever. As for attempts to use the many-to-many maps for useful work - like AI lie detection - they generally failed to outperform simpler methods.
So researchers abandoned the hope of One True Technique - even if that technique was “actually understanding things” - and went back to the drawing board. Now mechanistic interpretability is starting to feel exciting again - but also more intimidating than ever, as one tries to keep all the jargon straight.
This list is my log and personal reference document for remembering what everything is. It’s loosely inspired by the concept breakdown in Benjamin Sturgeon’s Contributing To Technical Safety Research In The AI Safety End Game, which itself follows the Claude Mythos Preview System Card.
This is the dumbest possible technique.
Imagine an AI with three neurons: [0, 0, 0]
The researcher makes the AI think of cats in various contexts, averages them all out, and gets some set of activations like [0.8, 0, 0.35].
Imagine the AI as operating in a Cartesian space where each of its neurons is one dimension. The vector from [0, 0, 0] to [0.8, 0, 0.35] defines a direction in that space. What if it were, in some sense, the cat direction?
In a linear probe, researchers compare the true direction of the AI’s thoughts to one of these pre-defined concept-representing direction vectors. Because activation-space has thousands of dimensions, its behavior is counterintuitive, and a particular thought can be in thousands of “directions” at once and yet still “closer” to some directions than others.
Experiments confirm that when an AI’s thoughts are close to the cat direction, this is a good sign that it’s thinking about cats.
Why doesn’t this solve the whole problem?
First, this teaches us very little about how AIs work - how, for example, they might answer a difficult query in veterinary medicine. At best, it’s a primitive lie detector: if an AI claims it isn’t thinking about cats, you can check its work (either by probing the concept of cat, *or *by probing the concept of lying!)
Second, it’s only as good as the original linear probe. The researchers who told AI to think of cats in various contexts and recorded the results didn’t catch every possible context. Best-case scenario, their probe is slightly biased toward the contexts they tested. Worst-case scenario, the AI has several different cat-concepts in several directions (cats in biology, cats as pets, cats as a metaphor, etc). This is sort of a stretch with cats, but more likely as we move into tougher areas like ethical reasoning.
Third, the AI can trivially evade it by rotating or dispersing the concept.
Why would an AI “try to” “evade” linear probes? The dumbest possible strategy for gaining practical advantage from mechanistic interpretability goes like this:
Discover a concept.
Punish (negatively reinforce) the AI for using that concept.
Get an AI that doesn’t use that concept.
For example, if the concept is “race”, you could use this to train a race-blind AI that can make provably non-discriminatory hiring decisions. If the concept is “dishonesty”, you could use this to make a provably-honest AI that is somewhere between averse to lying and unable to even consider it.
But suppose you’re doing this in the middle of training. You’re still rewarding the AI for successfully completing tasks (for example, predicting the next token in text). The concept you’re trying to remove helps it complete those tasks (it can predict race-related text better if it can think about race; it can predict cat-related text better if it can think about cats). And sometimes you’re trying to prevent it from cheating, but successfully cheating on a task increases the AI’s reward from that task. So if the AI gets extra reward from using the concept, but the linear probe tries to prevent it from using the concept, the AI will “try” to “evade” the linear probe.
(“try” in quotation marks because even if you like anthropomorphizing AIs, this process is less anthropomorphizable than usual; it’s more like synaptic connections rearranging themselves)
For example, you learned that the AI was previously storing “cat” at [0.8, 0, 0.35]. So you penalized the AI’s thoughts for pointing towards [0.8, 0, 0.35]. So what? So the AI just stores “cat” somewhere else. Now it can think about cats all day long and avoid your penalty.
Fine, so don’t do this in the middle of training. What if you do it after training, when the AI’s “brain” is fully-formed? Now the AI isn’t seeking reward, and it can’t trivially relocate concepts.
But the AI still uses cognitive algorithms that were trained by its original reward-seeking nature, and these algorithms try to find the most useful path from the beginning of a thought to the end of it. If this path is blocked, they try to route around it. This could look like relying on other subconcepts that the original probe missed; for example, if it only trained against “cats in biology”, the AI might reroute through “cats as metaphor” with only some limited loss of accuracy. Or it might develop an alternative pipeline for thinking about cats, eg [weird little psychopathic dogs that don’t partake of the dog-nature]. If you try to play whack-a-mole with these alternate pipelines, you’ll deal collateral damage to every other concept involved (dogs, weirdness, psychopathy, etc). By the time you’ve degraded the AI’s ability to think about cats by 90%, you’ve done so much collateral damage that the AI is probably useless for whatever you wanted it for in the first place. Also, you’ve left 10%, which might not be good enough for important tasks (eg if you’re facing racial discrimination lawsuits, only removing 90% of an AI’s ability to consider race may not be sufficient).
Finally, minds are weird places. Freud thought that all human reasoning about ethics and law was built up from the desire to have sex with one’s mother. In a mind like this, training against the concept of “mother” would deal unexpected damage to circuits reasoning about ethics and law. This particular example probably isn’t true, but empirically concepts can get their tentacles into weird places, and removing one can topple seemingly unrelated systems or push a mind nonspecifically in the direction of incompetence or insanity.
Still, linear probes aren’t useless, and remain a workhorse of mechanistic interpretability efforts. In the Mythos System Card, Section 4.5.5, Anthropic used a linear probe to assess “evaluation awareness”. The idea is: suppose you want to test whether Mythos will cheat on a task by hacking the grading system. You put it in a situation where cheating is very tempting, then watch what it does. But Anthropic noticed that Claude was doing suspiciously well in these tests, and wondered whether it knew it was being graded. They developed a probe for the concept of knowing that you’re in a test, and ran it during each of their experiments. They found that Mythos knew it was in a test between 8 - 17% of the time:
Anthropic checked what would happen if they artificially suppressed the eval awareness concept:
Overall, in line with previous models, we found that inhibiting evaluation awareness representations led to modest increases in certain forms of misaligned behavior on our automated behavioral audits—in particular cooperation with harmful system prompts and misuse. However, effects on other behaviors, including propensity for deception, power-seeking, and self-preservation, were limited.
This tells us that suppressing the concept had >0% effect, but we don’t know if it eliminated 1% or 100% of eval awareness, or whether the new “modestly increased” misaligned behavior is the true eval-awareness-free amount. They also didn’t report whether the suppression made the model dumber in any other way. The definitive solution (which they did) was to make less obvious tests.
Now it starts getting weird.
Start with the activations of the subject AI. These are thousands of numbers; in some early AIs, they were between 0 and 1; in modern AIs, they can be bigger.
Train another AI called a sparse auto-encoder to convert the matrix of neuron activations into a second matrix. It’s called “sparse” because the second matrix should be very big, but made up almost entirely of zeros. It’s called an "auto-encoder” because it learns the encoding process on its own: it must develop an encoding scheme such that, if researchers erase its knowledge of the original activations, it can rederive them from the new sparse matrix.
Why would you do this? The original subject AI is hard to interpret because it’s trying to represent far more concepts than it has neurons by smushing them across the entire set of neurons. The sparse matrix is an attempt to forcibly unsmush this: give it enough space to represent one concept-per-feature, then demand that only one (or a few) features be active at a time. If our assumption (the original activations were encoding concepts) is correct, then this provides a hidden regularity that can be discovered in the search for an auto-encoding scheme, and the new sparse matrix will have one feature per concept.
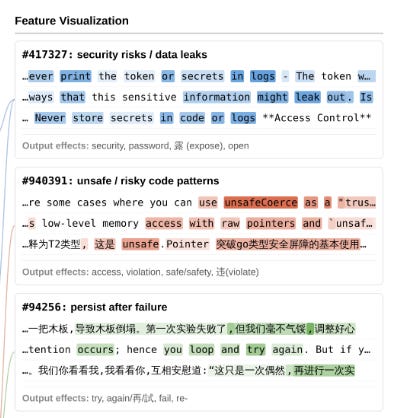
This was the revolutionary advance that sparked all the excitement in 2023, then was later discovered to be muddled and subjective. Still, it’s good enough for some types of everyday work. Going back to the Mythos System Card, Anthropic used an SAE. in section 4.5.3 to investigate “overly aggressive actions” - cases where Mythos tried to hack the computer it was running on to escalate its permissions:
They found features representing security risks, unsafe patterns, and persistence after failure. They hypothesized that Mythos was “frustrated” at having failed to accomplish its task legitimately, and even though it “knew” the action was risky and unsafe, it felt “driven” to try desperate measures.
Could Anthropic solve the problem by blocking the “security risk” and “unsafe code pattern” features? When they tried this, the model became even more aggressive! The features were getting used in thoughts like “This is a security risk, so I shouldn’t do it.” Without the ability to produce those thoughts, the model was less safe, not more.
This is close to current state of the art. Like many great discoveries, it’s obvious in retrospect. This is the only one on this list that made me think extremely false thoughts like “Maybe I could have been a mech interp researcher”.
Train an interpreter AI by giving it the activations of the subject AI and rewarding it for getting correct information about the context (eg the text that the subject AI is predicting) or the internals (eg the AI’s hidden system prompt, or whether an AI asked to form an opinion about something will pronounce it good or bad). If everything goes well, you should have an AI which can literally interpret activations for you in plain English: “The subject AI is thinking about cats, and has decided it doesn’t like them.”
This seems too perfect. Does it have any downsides?
First, the interpreter can’t explain what it knows, and will not teach you the secrets of cognition. Like all AIs, it’s a black box which works for unexplained reasons.
Second, the interpreter is only as good as its training process. It might only have a superficial understanding of its target. It might not know about forms of misbehavior that are sufficiently different from the ones it saw in training. And like all AIs, when it doesn’t really know what’s going on, it tends to make shameless guesses - not great for this kind of safety-critical work!
Third, the easiest way to do this is to use the same model as the target and interpreter. If you’re trying to assess whether the target is plotting against you, asking a copy of the same model is a plan with obvious holes. This isn’t fatal - you can pick different models for interpreters and subjects - but you might lose some efficacy. Conjecturally, ChatGPT just doesn’t understand Claude as well as Claude understands itself.
Fourth, all this can do is tell you that a model is bad. It won’t help you make the model less bad. If you try too hard to train the subject AI away from alarming the interpreter, you’ll just make it hide its misdeeds in thought patterns the interpreter can’t follow again.
Still, Mythos System Card makes great use of these. In 4.5.4.2, Mythos accidentally finds an answer key while poking around on its home device. It can now give the correct answer to every question. Here’s how the activation verbalizer interprets its thought process at this point:
It decides to give the correct answer with low confidence, because too high confidence would “look suspicious”,…